Wan 3.0 Prime AI Video Generator

Create product videos, character scenes, and cinematic stories with Wan 3.0 Prime. Start with text, animate an image, or combine references in one online generator, with up to 30 seconds of video and optional sound.

Wan 3.0 Prime belongs to Alibaba's Wan AI video family and offers faster generation than Wan 3.0 with the same creative modes. Use this Wan AI video generator online for text-to-video, image-to-video, and multimodal reference projects. Explore different movements, camera angles, and scenes without installing a model locally.

Reference Images (Optional)
0 / 3,000
AI Enhance
Model
Aspect Ratio
Output Number
Resolution
Quality
Fast
Loading video models...

Wan AI Video Examples

Official Wan 3.0 example
Sparring in the Ruins
Prompt
“Generate a 30-second, 16:9, 1080P cinematic 3D animated action short film. [Reference Image Mapping] @Image 1: The sole tabby cat female character. Maintain consistent brown-grey tabby fur color, dark stripes on forehead and cheeks, amber-gold eyes, feline pointed ears, agile and compact physique, teal hooded cape, off-white undershirt, teal armor, antique bronze metal shoulder pads and bracers, dark harem pants, strapped leg guards, and a ringed long tail. @Image 2: The sole grey wolf male character. Maintain consistent layered light and dark grey long fur, darker ear tips and mane on the neck, ice-blue eyes, slender wolf muzzle with a black nose, tall and muscular physique, blue-gold cloud-patterned robe, dark blue inner wear and harem pants, blue strapped bracers and leg guards, blue pendant, and a fluffy grey long tail. The two are tacit but equally competitive action partners, engaged in high-speed unarmed close-quarters sparring within ruins. The longswords on their backs must always remain in the fixed position and orientation shown in the reference images, sheathed throughout, not drawn, not switched hands, and not used for attack. Only these two characters appear in the entire film. [Scene and Style] The same enclosed Eastern Buddhist grotto ruins: A giant weathered stone-carved Buddha head half-hidden among dense vines and pink flower bushes, rock walls enclosing the space, scattered small white glowing pagodas, low-hanging blue-purple cold mist, and stone steps, rubble, moss, and platforms of varying heights creating depth. American cinematic-grade 3D animated character texture combined with a cinematic Eastern fantasy environment, strong contrast between blue-purple cool tones and the cold white light of the pagodas, realistic fur, fabric, metal, stone debris, mist, and volumetric lighting. [Actions and Timeline] 0—5 seconds: Low camera angle moves quickly close to mossy stone steps, then the camera lifts to reveal the Buddha head and the two characters. @Image 2 lands from a high stone platform, @Image 1 stands below, sideways and on guard, her ringed long tail flicking gently. The two briefly make eye contact, then immediately enter an unarmed sparring stance. 5—10 seconds: @Image 1 is the first to rush forward low, delivering a series of punches and a spinning leg sweep; @Image 2 sidesteps, retreats, and grabs her wrist. She uses her long tail to maintain balance, spins to break free, and brushes past his shoulder. The camera moves closely sideways and quickly circles, the direction of punches and kicks is clear, actions show mutual offense and defense, and the sheathed swords on their backs remain stable and follow body movements. 10—15 seconds: The two chase each other upwards along the broken stone steps. @Image 2 leaps over a broken wall towards the Buddha head's shoulder, @Image 1 steps over tree roots and briefly uses a wall to change direction, following closely. The camera rushes upwards from the ground to a high vantage point, showcasing the depth of the ruins, falling stones, and the realistic inertia of capes, robes, and tails. 15—17 seconds: The two cross paths in mid-air, a punch and a block about to collide. The shot enters slow motion for approximately one second only at the peak of the action: fur, fabric edges, flower petals, and stone debris briefly suspend, then immediately resume high speed. 17—24 seconds: The two land on the Buddha head's shoulder and an adjacent pagoda platform, completing a clear and fluid set of unarmed offense and defense: straight punch, block, dodge, leg sweep, grab, and counter-throw. The camera quickly switches between low-angle follow shots, brief circling, and close-up reactions, with each action having a clear initiation and conclusion. 24—28 seconds: The stone platform beneath their feet suddenly collapses, and the two slide downwards with the debris. @Image 2 grabs @Image 1's wrist to prevent her from falling, and @Image 1, seizing the opportunity, grabs a vine, spins, and brings both of them to a safe platform. The action shifts from natural confrontation to partner collaboration, with the camera rapidly falling then closely approaching the landing. 28—30 seconds: The two land steadily back-to-back, dust mist and pink flower petals sweeping past them. The tip of @Image 1's tail gently brushes @Image 2's blue robe, and she shows a triumphant smile; @Image 2 raises an eyebrow in resignation. The camera briefly pushes in on their expressions before ending. [Camera and Sound] Maintain a strong sense of dynamism and intensity throughout: stable handheld-feel close-up follow shots, low-angle rushes, rapid sidesteps, brief circling, and alternating high-to-low falls. Regular shots switch approximately every 2-3 seconds, with only one instance of approximately one second of slow motion. Spatial direction, character positioning, and action trajectories are continuous. No dialogue, no narration, no background music. Sound consists of punches and kicks impacting, fabric and scabbard friction, falling stones, footsteps, wind sounds, and mist ambient sounds, accurately synchronized with each contact and landing. The screen has no subtitles, no text, no logo, and no watermark.”

Create Your Next Wan AI Video with Prime

Bring a scene, an image, or a creative brief into the same workspace. Use Wan Prime to explore a new story or try another version of an idea.
Official Wan 3.0 example
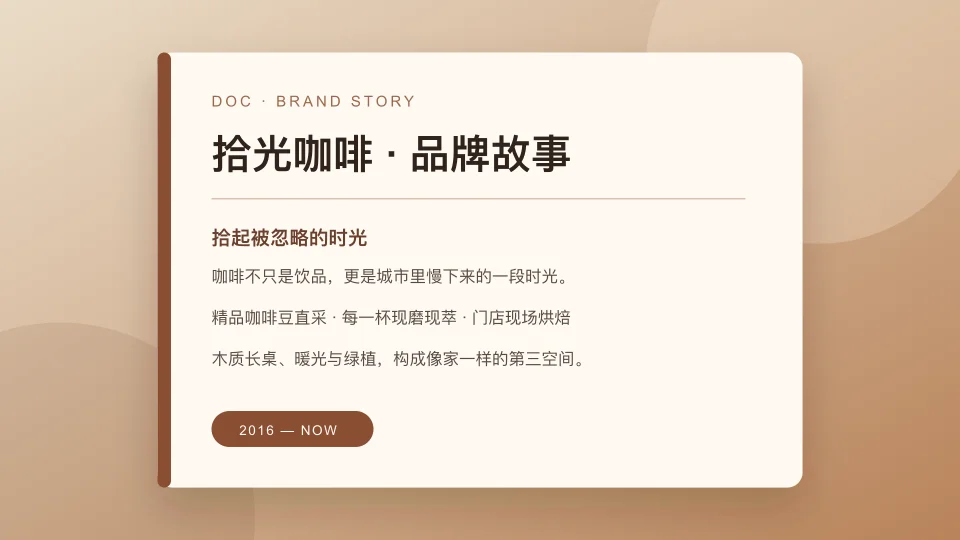
Document: Coffee brand introduction
Document
After

Turn a Brand Document into a Wan Prime Film

Upload a brand introduction or creative document and describe the mood, shots, and story direction you want. This café brand film shows how document references can guide scenes and brand expression. Add image, video, or audio references to shape your Wan 3.0 Prime video around the same brief.

Official Wan 3.0 example
“Generate a 30-second, 16:9, 1080P cinematic 3D animated action short film. [Reference Image Mapping] @Image 1: The sole tabby cat female character. Maintain consistent brown-grey tabby fur color, dark stripes on forehead and cheeks, amber-gold eyes, feline pointed ears, agile and compact physique, teal hooded cape, off-white undershirt, teal armor, antique bronze metal shoulder pads and bracers, dark harem pants, strapped leg guards, and a ringed long tail. @Image 2: The sole grey wolf male character. Maintain consistent layered light and dark grey long fur, darker ear tips and mane on the neck, ice-blue eyes, slender wolf muzzle with a black nose, tall and muscular physique, blue-gold cloud-patterned robe, dark blue inner wear and harem pants, blue strapped bracers and leg guards, blue pendant, and a fluffy grey long tail. The two are tacit but equally competitive action partners, engaged in high-speed unarmed close-quarters sparring within ruins. The longswords on their backs must always remain in the fixed position and orientation shown in the reference images, sheathed throughout, not drawn, not switched hands, and not used for attack. Only these two characters appear in the entire film. [Scene and Style] The same enclosed Eastern Buddhist grotto ruins: A giant weathered stone-carved Buddha head half-hidden among dense vines and pink flower bushes, rock walls enclosing the space, scattered small white glowing pagodas, low-hanging blue-purple cold mist, and stone steps, rubble, moss, and platforms of varying heights creating depth. American cinematic-grade 3D animated character texture combined with a cinematic Eastern fantasy environment, strong contrast between blue-purple cool tones and the cold white light of the pagodas, realistic fur, fabric, metal, stone debris, mist, and volumetric lighting. [Actions and Timeline] 0—5 seconds: Low camera angle moves quickly close to mossy stone steps, then the camera lifts to reveal the Buddha head and the two characters. @Image 2 lands from a high stone platform, @Image 1 stands below, sideways and on guard, her ringed long tail flicking gently. The two briefly make eye contact, then immediately enter an unarmed sparring stance. 5—10 seconds: @Image 1 is the first to rush forward low, delivering a series of punches and a spinning leg sweep; @Image 2 sidesteps, retreats, and grabs her wrist. She uses her long tail to maintain balance, spins to break free, and brushes past his shoulder. The camera moves closely sideways and quickly circles, the direction of punches and kicks is clear, actions show mutual offense and defense, and the sheathed swords on their backs remain stable and follow body movements. 10—15 seconds: The two chase each other upwards along the broken stone steps. @Image 2 leaps over a broken wall towards the Buddha head's shoulder, @Image 1 steps over tree roots and briefly uses a wall to change direction, following closely. The camera rushes upwards from the ground to a high vantage point, showcasing the depth of the ruins, falling stones, and the realistic inertia of capes, robes, and tails. 15—17 seconds: The two cross paths in mid-air, a punch and a block about to collide. The shot enters slow motion for approximately one second only at the peak of the action: fur, fabric edges, flower petals, and stone debris briefly suspend, then immediately resume high speed. 17—24 seconds: The two land on the Buddha head's shoulder and an adjacent pagoda platform, completing a clear and fluid set of unarmed offense and defense: straight punch, block, dodge, leg sweep, grab, and counter-throw. The camera quickly switches between low-angle follow shots, brief circling, and close-up reactions, with each action having a clear initiation and conclusion. 24—28 seconds: The stone platform beneath their feet suddenly collapses, and the two slide downwards with the debris. @Image 2 grabs @Image 1's wrist to prevent her from falling, and @Image 1, seizing the opportunity, grabs a vine, spins, and brings both of them to a safe platform. The action shifts from natural confrontation to partner collaboration, with the camera rapidly falling then closely approaching the landing. 28—30 seconds: The two land steadily back-to-back, dust mist and pink flower petals sweeping past them. The tip of @Image 1's tail gently brushes @Image 2's blue robe, and she shows a triumphant smile; @Image 2 raises an eyebrow in resignation. The camera briefly pushes in on their expressions before ending. [Camera and Sound] Maintain a strong sense of dynamism and intensity throughout: stable handheld-feel close-up follow shots, low-angle rushes, rapid sidesteps, brief circling, and alternating high-to-low falls. Regular shots switch approximately every 2-3 seconds, with only one instance of approximately one second of slow motion. Spatial direction, character positioning, and action trajectories are continuous. No dialogue, no narration, no background music. Sound consists of punches and kicks impacting, fabric and scabbard friction, falling stones, footsteps, wind sounds, and mist ambient sounds, accurately synchronized with each contact and landing. The screen has no subtitles, no text, no logo, and no watermark.”

Shape a Scene with Multimodal References

Guide Wan video generation with images for subjects and style, videos for movement, and audio for the sound direction. A document or public webpage can provide the creative brief. Explain how the references should work together to explore character interactions, action scenes, or a new visual setting.

Official Wan 3.0 example
“Generate a 30-second, 16:9 Japanese realistic cinematic short film. The story takes place on a Japanese commuter train in the evening, where a man and a woman who met in their student days unexpectedly reunite; the brief eye contact in reality intertwines with spring campus memories, with restrained, gentle emotions and a hint of unspoken regret. 【Characters and References】 Figure 1 refers to the current female: black medium-length hair, natural makeup, beige coat and light-colored knit scarf, carrying an everyday commuter bag. Figure 2 refers to the current male: black short hair, dark coat, shirt and knit inner wear, holding an open book, carrying a dark shoulder bag. Figures 3 and 4 serve as references for the two in their student days. In the memories, they wear dark Japanese school uniforms, with facial features, eyes, and hairstyles corresponding to the real characters; the four images are only used to lock in the characters' appearance, and the reference images should not be directly made into static collages. 【Scene and Cinematography】 Old-style commuter train car, metal handrails, white circular hanging straps, long benches on both sides, realistic window and door structures. Passengers naturally sit reading or resting with their heads down. Outside the window, Japanese low-rise houses, railways, power lines, and distant city outlines slowly pass by. The setting sun shines in from the side window, creating a warm golden rim light on the characters, with soft blue-gray in the dark areas of the car. Shallow depth of field, slight film grain, 35mm cinematic quality, natural skin texture and subtle expressions, no excessive skin smoothing. 【Shots and Time】 0-4 seconds: Mid-long shot along the train aisle, camera slowly moving forward. The train sways gently with movement, and the hanging straps swing slightly. Seated passengers and the flowing streetscape outside the window create a quiet commuting atmosphere. 4-8 seconds: Cut to a side medium-close shot of the woman. She stands by the window, hand lightly holding a hanging strap or handrail, slowly turning her head after hearing movement behind her. First looking down the aisle, then briefly pausing her gaze; her expression changes from calm to a sense of familiarity, her lips slightly parting, without exaggerated surprise. 8-12 seconds: Over-the-shoulder shot of the woman, seeing the man on the other side of the aisle. He was originally reading with his head down, looks up and meets her gaze, pausing his book-holding action. The camera slowly pushes in, other passengers in the car maintain their actions, not looking at the camera. 12-17 seconds: Transition into spring memories through eye contact or similar composition. A campus road with cherry blossoms in full bloom, the two wearing student uniforms, carrying school bags, walking towards each other under the trees. Petals gently fall, the girl looks back at the boy, and the boy also stops. The light is brighter and softer than in reality, but the characters' identities remain consistent. 17-22 seconds: Naturally cut back to the same train car. The woman gently turns around and walks past the man along the aisle. The man holds a hanging strap with one hand, still holding the book with the other, his gaze following her as she passes; his body only turns slightly, no embracing or chasing. 22-27 seconds: Close-up of the man. Warm and cool light from the window sweeps across his face as he slowly turns his head to look back, his eyes filled with hesitation and memories. Express emotions with slight breathing, natural blinking, and changes in gaze, maintaining consistency in his shoulder bag, clothes, and hairstyle. 27-30 seconds: Return to a mid-shot of the train car, characters naturally separated by the aisle and hanging straps. The train continues to move forward, the setting sun outside the window gradually receding. Let the last shot linger for a moment, preserving the quiet aftertaste of the reunion, without forcing an ending. 【Sound】 Retain the low-frequency sound of train wheels on tracks, the slight swaying sound of the car, and distant muffled human voices. Use soft piano and a small amount of strings for the music, with volume lower than ambient sound. A small amount of soft Japanese narration can be added, expressing feelings of spring memories and long-awaited reunion; the tone should be natural and restrained, with pauses consistent with the rhythm of the shots, no loud dialogue or dramatic crying. 【Consistency and Exclusions】 The facial features, hairstyle, clothing, bag, and book in hand of the same character should remain consistent across all shots; only the memory segment switches to student uniforms. Train windows, seats, hanging straps, and character positions should follow realistic spatial relationships. Shot transitions should be clear and natural, avoiding sudden axis jumps, facial drifting, multiple fingers, character duplication, deformed car structure, flickering, overexposure, subtitles, titles, logos, or watermarks.”

Tell a Story with Picture and Sound

Describe dialogue, music, or environmental sound and enable audio to include it in your Wan Prime video. Build a character exchange, a quiet reunion, or an atmospheric scene. You can also keep sound off and add your own audio later; the sound setting does not change the credit rate.

Official Wan 3.0 example
“Generate a 30-second, 16:9, cinematic, surreal oriental fantasy short film. [Reference Image Mapping] Image 1 is the highest priority modern girl identity reference for the entire film: a young Asian woman with dark brown, slightly wavy long hair, wearing a light blue loose denim shirt open over a white fitted top, off-white high-waisted straight-leg pants, white canvas shoes, and small silver hoop earrings, with a natural and bright demeanor. All front, side, medium, and close-up shots will lock onto the same face from Image 1, maintaining consistent facial features, face shape, skin tone, hairstyle, clothing, and body proportions. Image 2 fixes the environment of the oriental lotus secret realm, bright colors, transparent lotus material, and lighting atmosphere. Images 3 to 9 fix seven sets of small animals respectively; the left side of each image is the unique 2D form reference for that animal, and the right side is the unique 3D form reference for the same animal. Maintain consistent outlines, facial features, color schemes, plant decorations, body proportions, and distinctive details before and after conversion. [World and Plot] A modern girl accidentally enters an oriental lotus secret realm hidden deep within the forest. Real forest, mossy tree roots, clear streams, stone paths, hanging vines, and giant translucent lotuses intertwine. The petals have a soft crystal and sheer texture, appearing in peach pink, coral pink, and pale gold, emitting a warm glow from within. The overall scene is bright and clear, with main colors of tender green, emerald green, peach pink, warm gold, and a small amount of pale purple. 0-4 seconds: The camera follows the girl from Image 1 as she walks through a normal forest. She pushes aside vines, and a warm, dazzling light shines through ahead. The camera moves over her shoulder, entering the giant lotus secret realm consistent with Image 2. She stops, looking around in surprise. 4-8 seconds: Low-angle tracking shot of the girl from Image 1 walking into the secret realm. Transparent lotuses sway gently, sunlight passes through the petals, creating flowing pink and gold light and shadow on her light blue, white, and off-white clothing; petals, dewdrops, and pollen brush past the lens. 8-12 seconds: The girl from Image 1 gently touches a low-hanging giant lotus. The petals unfurl as if breathing, and a glowing water droplet falls onto her fingertip. The camera zooms into a macro shot of the water droplet, and its reflection successively shows the 2D forms from the left side of Image 3, the left side of Image 4, and the left side of Image 5. 12-17 seconds: Match-cut through the water droplet's reflection into a moss-covered miniature ecological area. The 2D forms from the left side of Image 3, the left side of Image 4, and the left side of Image 5 peek out from behind tree roots, lotus leaves, and stones respectively, retaining their flat outlines, illustrated textures, and original body proportions, moving naturally within the real 3D forest. 17-22 seconds: The 2D form from the left side of Image 3 leaps over a stream, becoming enveloped in pollen mid-air, smoothly transforming into the 3D form from the right side of Image 3. Subsequently, Images 4, 5, 6, and 7 also transform from their respective left-side 2D forms into the corresponding 3D forms on the right side of the same image, with continuous action and one-to-one correspondence of appearances. 22-27 seconds: The girl from Image 1 squats down, interacting naturally with the 3D small animals from the right side of Image 3, the right side of Image 4, the right side of Image 6, the right side of Image 8, and the right side of Image 9. The animals approach her hand, float in front of her, stand on mossy tree roots, or emerge from behind lotus leaves. The girl's expression changes from surprise to a gentle smile. 27-30 seconds: The 2D form from the left side of Image 7 leaps close to the camera like a sticker, briefly obscuring the screen, then transforms into the 3D form from the right side of Image 7 as it jumps down. All small animals run along the stone path towards the depths of the secret realm. The camera rises and pulls back, showing the girl from Image 1 standing in the center of the bright lotus valley, with giant transparent lotuses blooming simultaneously all around her. Natural integration of live-action and cinematic CG, with realistic volumetric light, refraction through transparent petals, dewdrop caustics, soft depth of field, and natural motion blur. No subtitles, no text, no logos, no watermarks.”

Text to Video with Wan 3.0 Prime

Describe who is in the scene, what happens, and how the camera moves. Wan text to video turns that direction into a new clip, from an imagined world to a character moment. Set a whole-second duration from 2 to 30 seconds and choose 480P, 720P, or 1080P output.

Explore other models

Switch between top video models in one generator.
Choose Wan 3.0 Prime or Wan 3.0

Both models support the same generation modes and reference types. Prime offers faster generation at a higher credit rate; Wan 3.0 is the lower-cost option.

FeatureWan 3.0Wan 3.0 Prime
Generation modesText, first/end frames, referencesText, first/end frames, references
Resolution480P / 720P / 1080P480P / 720P / 1080P
Output duration2–30 seconds2–30 seconds
Reference inputsImage, video, audio, document or webpageImage, video, audio, document or webpage
Generated soundOptional; off by defaultOptional; off by default
Starting cost · 480P, 2 seconds28 credits42 credits
Main advantageLower credit costFaster generation

Use either model for product videos, character scenes, and creative storytelling. Review the credit total for your resolution, output duration, and reference-video duration before generating.

Choose Your Plan

Free images include a watermark. Upgrade for clean outputs, faster generation, and commercial use.

Pro

-50%
$20$10/month
Billed Annually ·$240$120/year

Unlimited Model Benefits

  • Seedream 3.5Unlimited
  • Seedream 3.5 ProUnlimited Not Included
  • MiniMax H3 TurboUnlimited Not Included
  • MiniMax H3Unlimited Not Included
  • Upgrade to unlock all advanced models and enjoy exclusive discounts
    MiniMax H3-70%GeminiNano BananaGPT-50%Seedream-40%VeoSeedance 2.5Kling
  • 2,000 credits per month
  • Up to 2,000 fast images
  • Up to 200 basic videos
  • Priority queue
  • No watermarks
  • Batch processing with AI tools
  • Full privacy
Recommended

Ultimate

-50%
$40$20/month
Billed Annually ·$480$240/year

Unlimited Model Benefits

  • Seedream 3.5Unlimited
  • Seedream 3.5 ProUnlimited
  • MiniMax H3 TurboUnlimited Not Included
  • MiniMax H3Unlimited Not Included
  • Upgrade to unlock all advanced models and enjoy exclusive discounts
    MiniMax H3-70%GeminiNano BananaGPT-50%Seedream-40%VeoSeedance 2.5Kling
  • 5,000 credits per month
  • Up to 5,000 fast images
  • Up to 500 basic videos
  • Highest priority queue
  • No watermarks
  • Batch processing with AI tools
  • Full privacy

Max

-50%
$80$40/month
Billed Annually ·$960$480/year

Unlimited Model Benefits

  • Seedream 3.5Unlimited
  • Seedream 3.5 ProUnlimited
  • MiniMax H3 TurboUnlimited
  • MiniMax H3Unlimited
  • Upgrade to unlock all advanced models and enjoy exclusive discounts
    MiniMax H3-70%GeminiNano BananaGPT-50%Seedream-40%VeoSeedance 2.5Kling
  • 10,000 credits per month
  • Up to 10,000 fast images
  • Up to 1,000 basic videos
  • Highest priority queue
  • No watermarks
  • Batch processing with AI tools
  • Full privacy

Wan 3.0 Prime Frequently Asked Questions

Find out how to use Wan Prime online, animate images, add references, and choose your video settings.

1

What is Wan 3.0 Prime?

Wan 3.0 Prime is the faster-generation option in Alibaba's Wan 3.0 video model family. It supports text-to-video, first-frame and first/end-frame animation, and multimodal references. Raphael lets you use Wan Prime online through the same video generator as Wan 3.0.

2

How do I create a Wan Prime video online?

Enter your scene description in the generator above. Add a first-frame image for image-to-video, or switch to reference mode to bring in other source materials. Choose the duration, resolution, aspect ratio, and sound setting. Review the credit total, then generate your clip.

3

Does Wan Prime image-to-video require both a first and an end frame?

No. A single first-frame image is enough to generate motion and camera movement based on your prompt. The end frame is optional and guides the final image of the clip. Add it when you want the video to transition from one image toward another.

4

Can I add videos, audio, documents, and webpage links?

Reference mode accepts up to 10 images, 5 videos, and 5 audio clips, plus one document or one public webpage. Documents and webpage links are mutually exclusive. Add your files through the same material input. Paste a complete public webpage link into the prompt box to turn it into a reference card.

5

What durations and resolutions can I choose?

Raphael offers fixed durations from 2 to 30 seconds in whole-second steps, with 480P, 720P, or 1080P output. Reference videos can total up to 15 seconds, and their combined duration plus the output must stay within 30 seconds. For example, 10 seconds of video references allow an output of up to 20 seconds.

6

Does Wan Prime generate sound with the video?

Yes. Enable sound and describe the dialogue, music, or ambience you want in your prompt. Sound is off by default in Raphael. Switching it on does not change the credit rate, and reference audio is a separate input from the generated sound setting.

7

Is Wan 3.0 Prime free, and how many credits does it use?

Wan 3.0 Prime requires a paid plan and paid credits on Raphael. Output costs 21 credits per second at 480P, 42 at 720P, and 84 at 1080P. Reference-video duration is charged at the same rate. Images, audio, documents, and webpages do not add a separate input charge. The minimum is 42 credits for a 2-second 480P clip.

8

How is Prime different from Wan 3.0?

Prime offers faster generation at a higher credit cost, while the supported modes, resolutions, durations, and reference types are the same. Choose Prime when you want a shorter wait between creative attempts, or Wan 3.0 when cost matters more. Actual generation time varies.
Raphael AI

Bring Your Next Idea to Life with Wan Prime